3x Faster Than Typing
Speak 150+ words per minute vs 40 wpm typing. Finish tasks in a third of the time.
Document pipelines, debug faster, ship reliable data
Read this example aloud, or say something of your own.
Your voice. Right where you work.
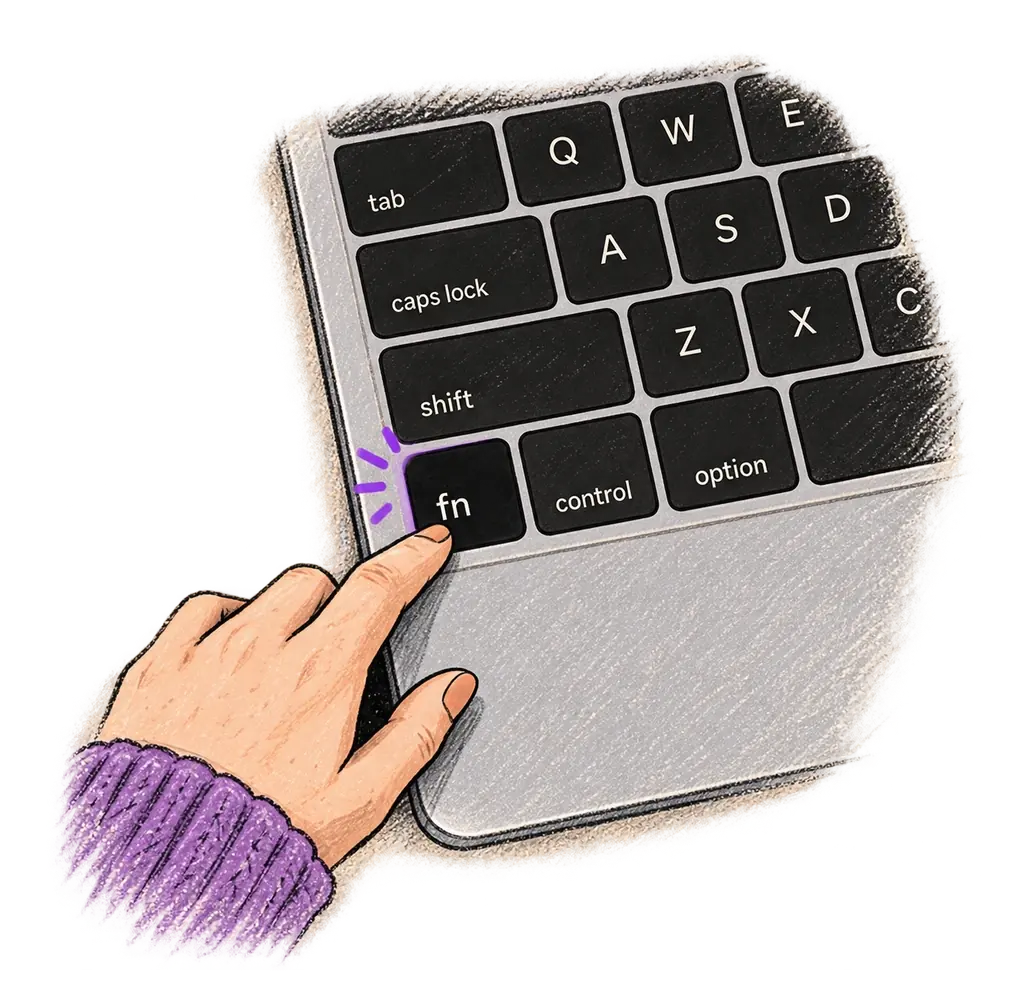
Place your cursor in any app, then hold the Fn key.
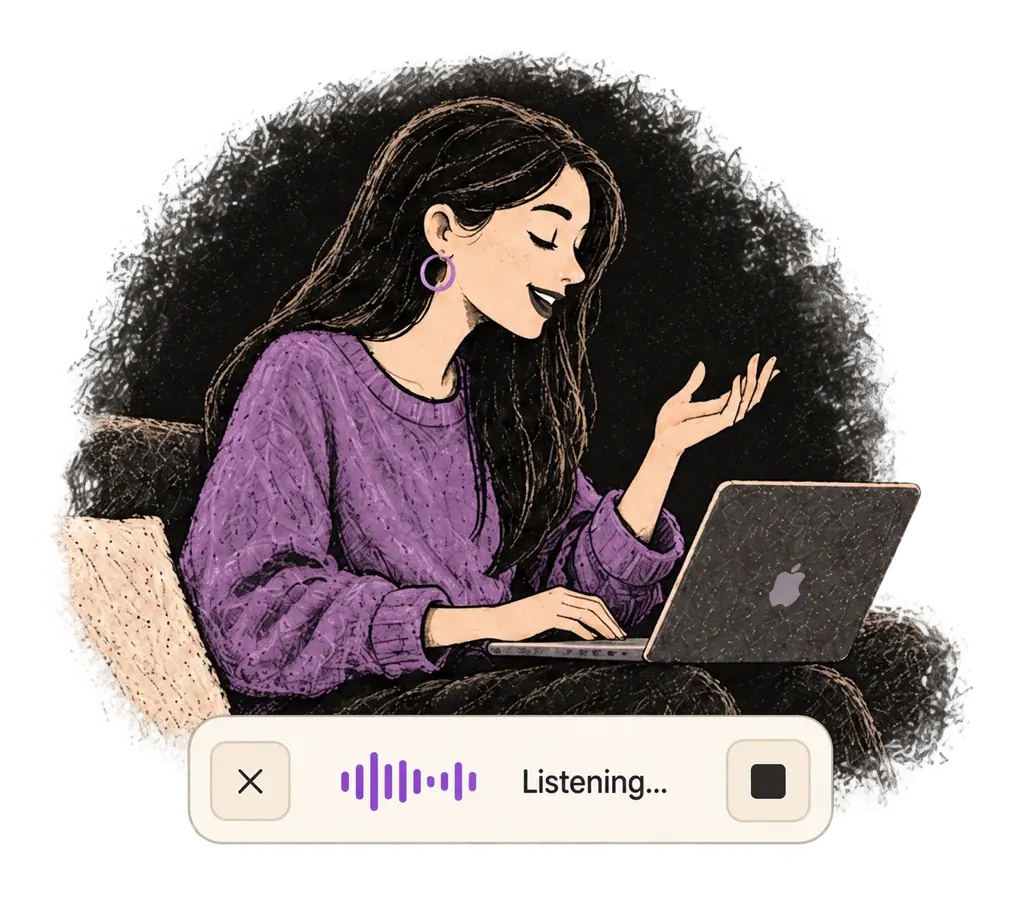
Say what you want to write. Ottex follows your saved writing rules.
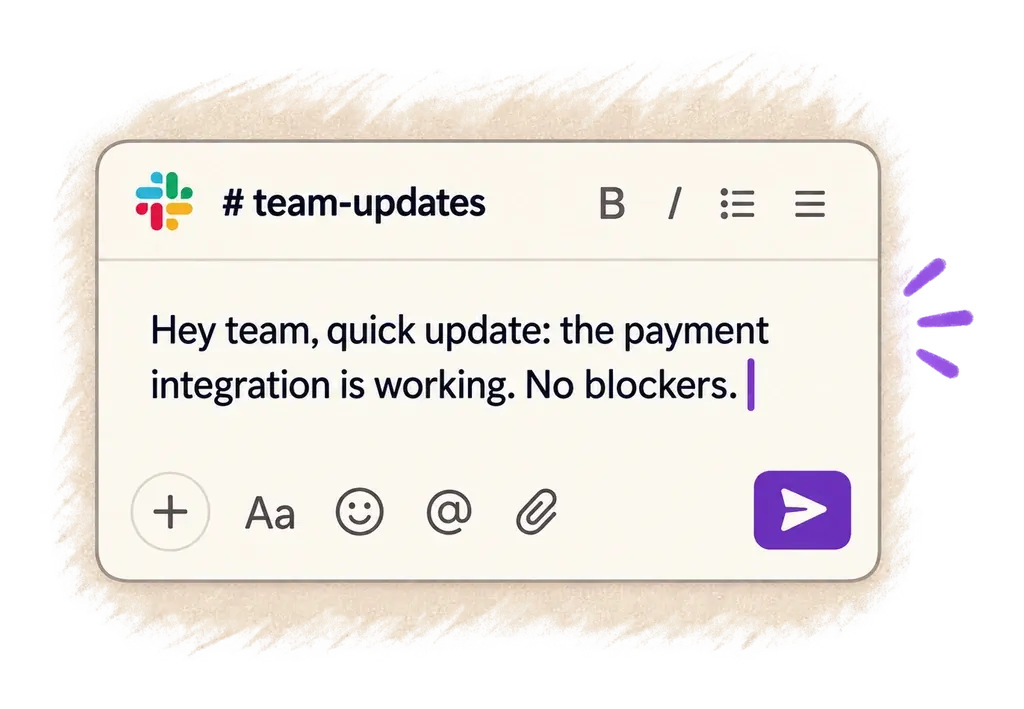
Your text appears right where your cursor is.
Concrete benefits with real-world impact
Speak 150+ words per minute vs 40 wpm typing. Finish tasks in a third of the time.
Speaking naturally gives AI agents more context than typing. Describe your intent, explain edge cases, mention file names—your voice carries nuance that typing shortcuts.
Cloud AI models excel at technical jargon, code terminology, and specialized vocabulary.
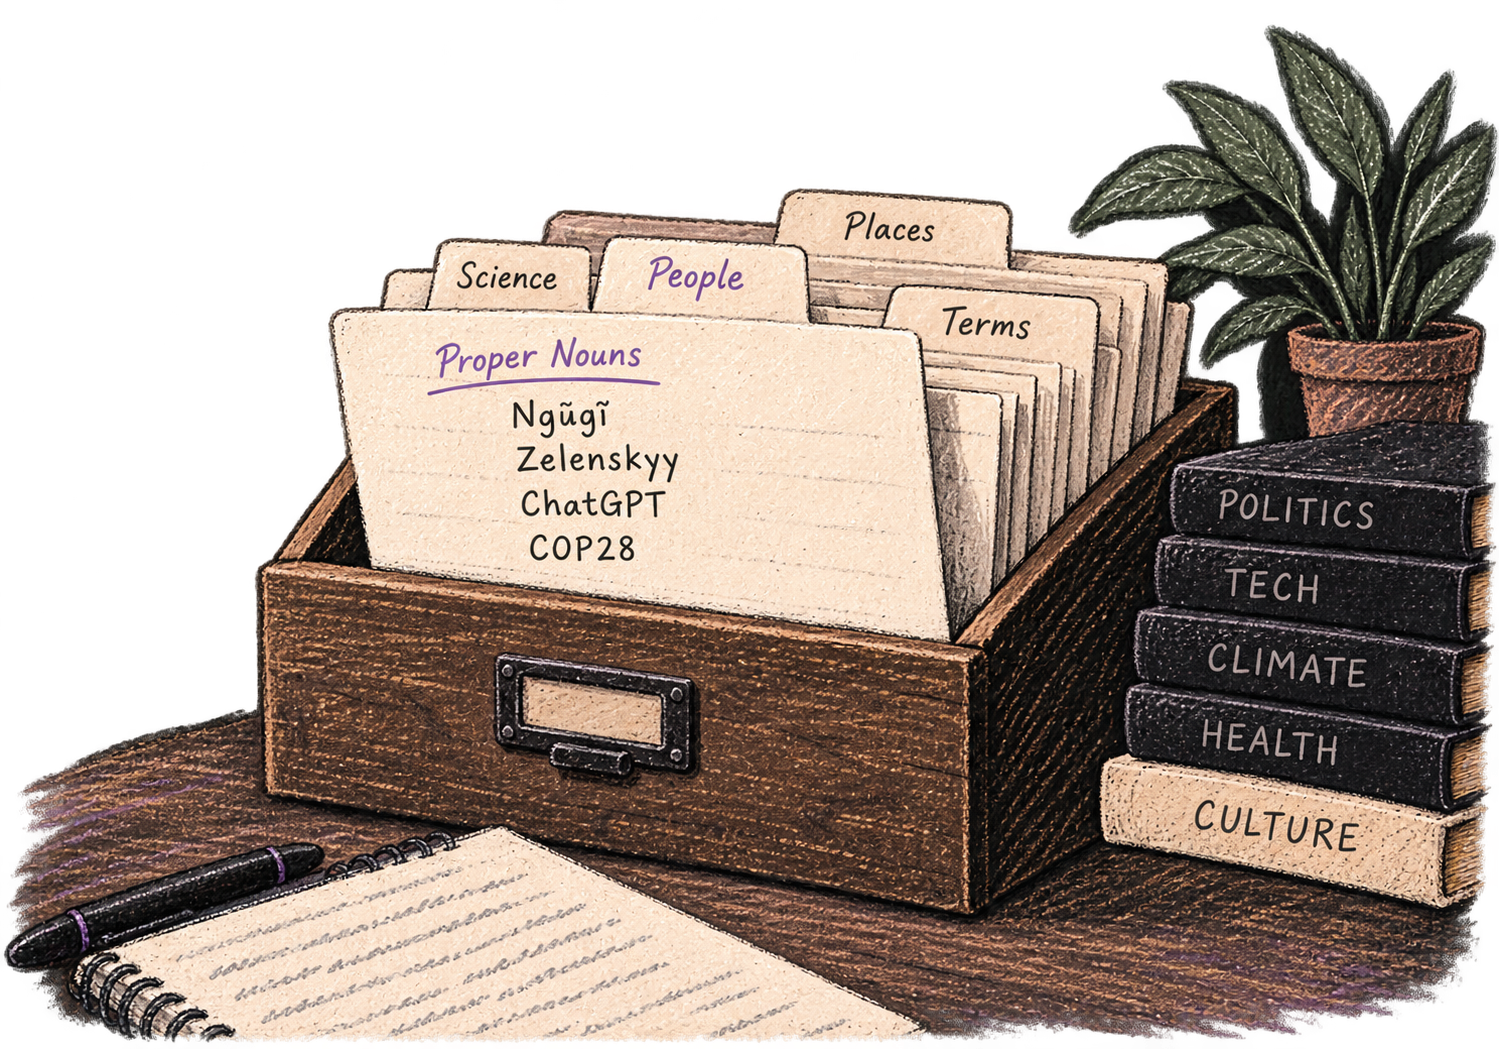
Add names, technical terms, and jargon. Ottex transcribes them accurately every time.
Transform text as you speak: 'Ottex start fix grammar Ottex end'. Edit, improve, translate—all by voice.
Say 'new paragraph', 'open quote', 'em dash', 'ellipsis'. Full formatting control by voice.
Dictate prompts to ChatGPT, Claude, Perplexity—anywhere you type. Better prompts, better answers.
Say 'scratch that' to delete mistakes, 'actually' to rephrase. Fix errors without stopping your flow or touching the keyboard.
Start recording with Option+D, use Push-to-Talk, or cancel with Esc. All shortcuts are fully configurable.
System-wide on macOS—Ottex works wherever you can type. No app-specific integrations needed.
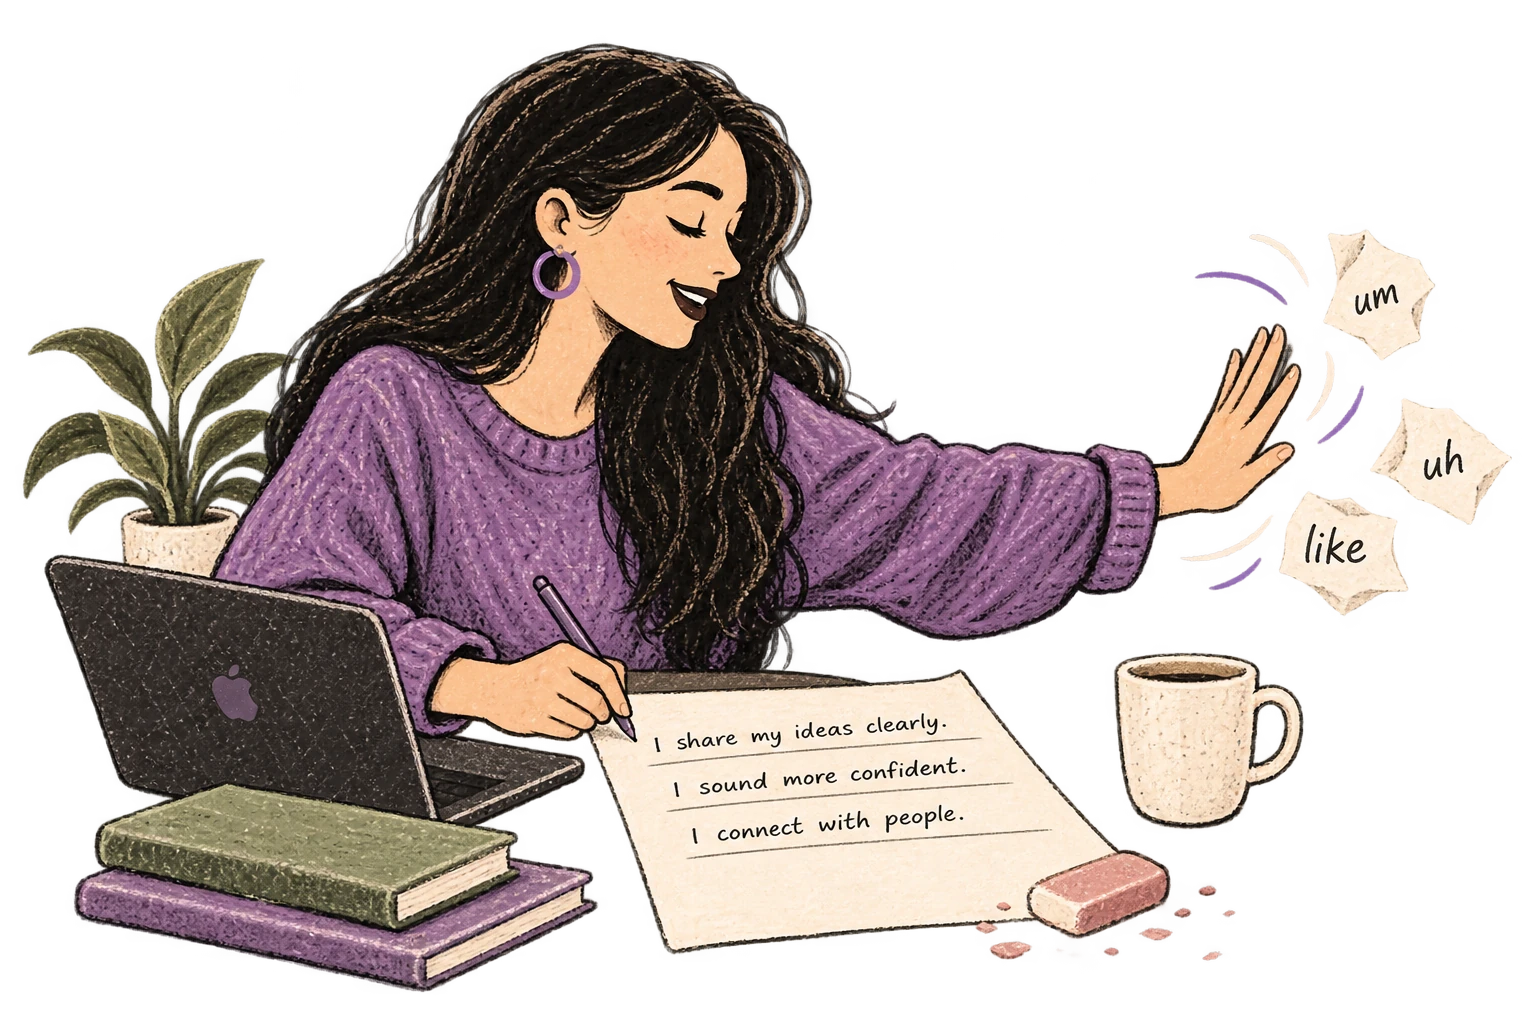
Automatically removes filler words like 'um', 'uh', 'like', 'so' from your transcription. Get clean, professional text without verbal hesitations.
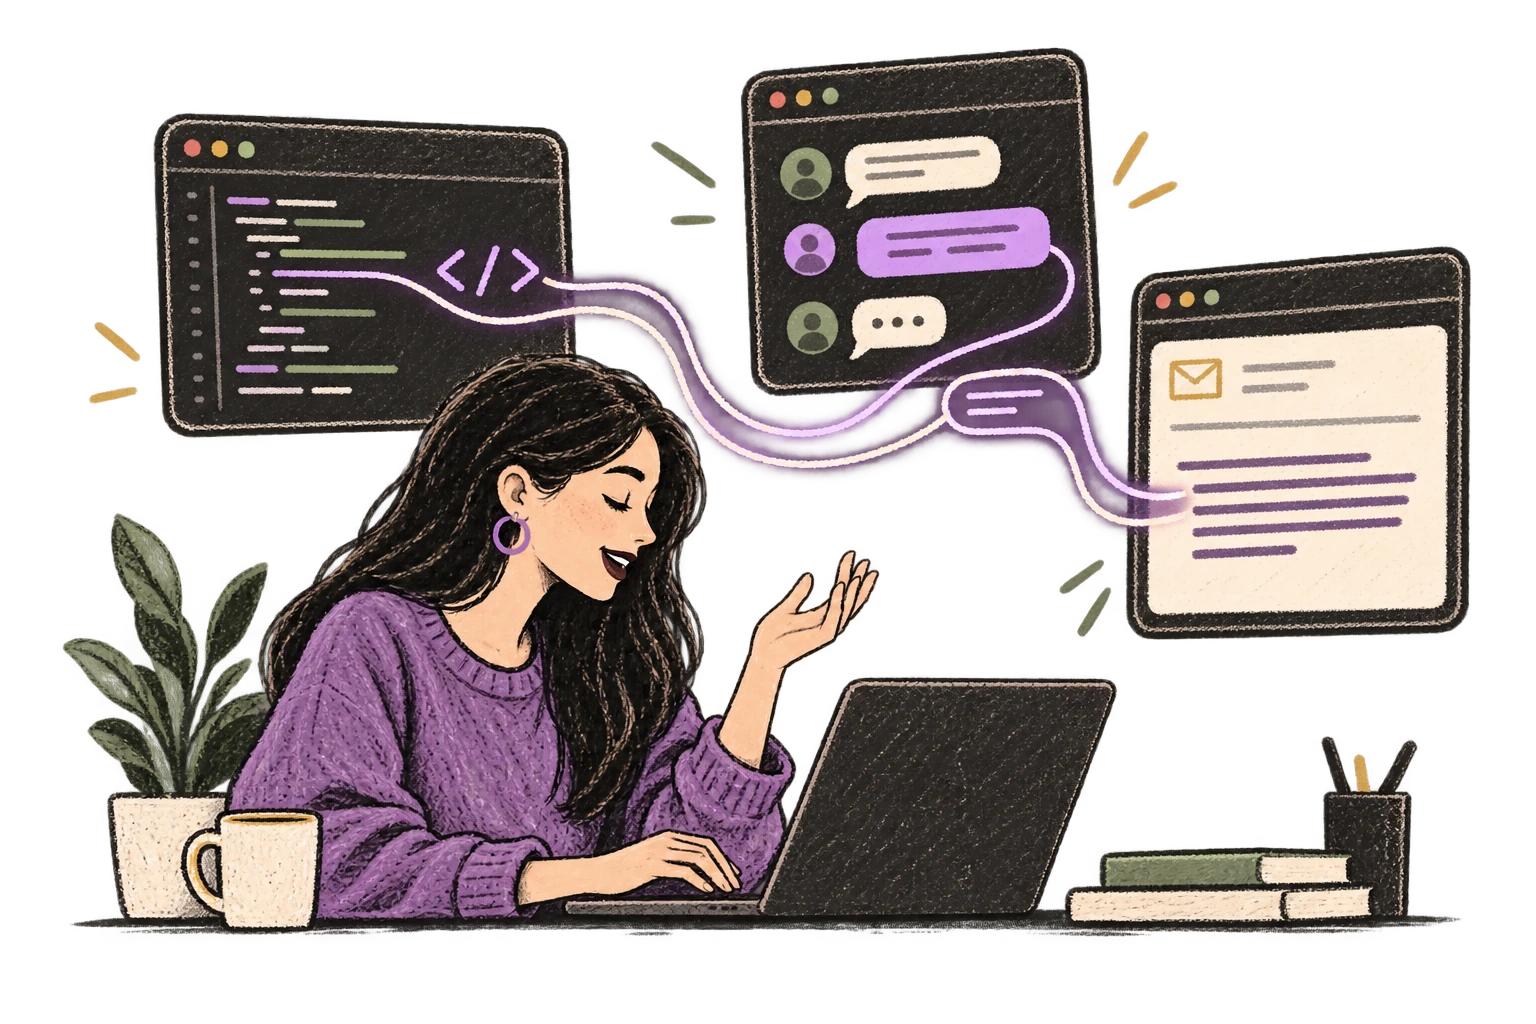
Ottex detects which app you're in and adapts. Coding mode in Cursor, casual tone in Slack, professional in Gmail—automatic context switching.
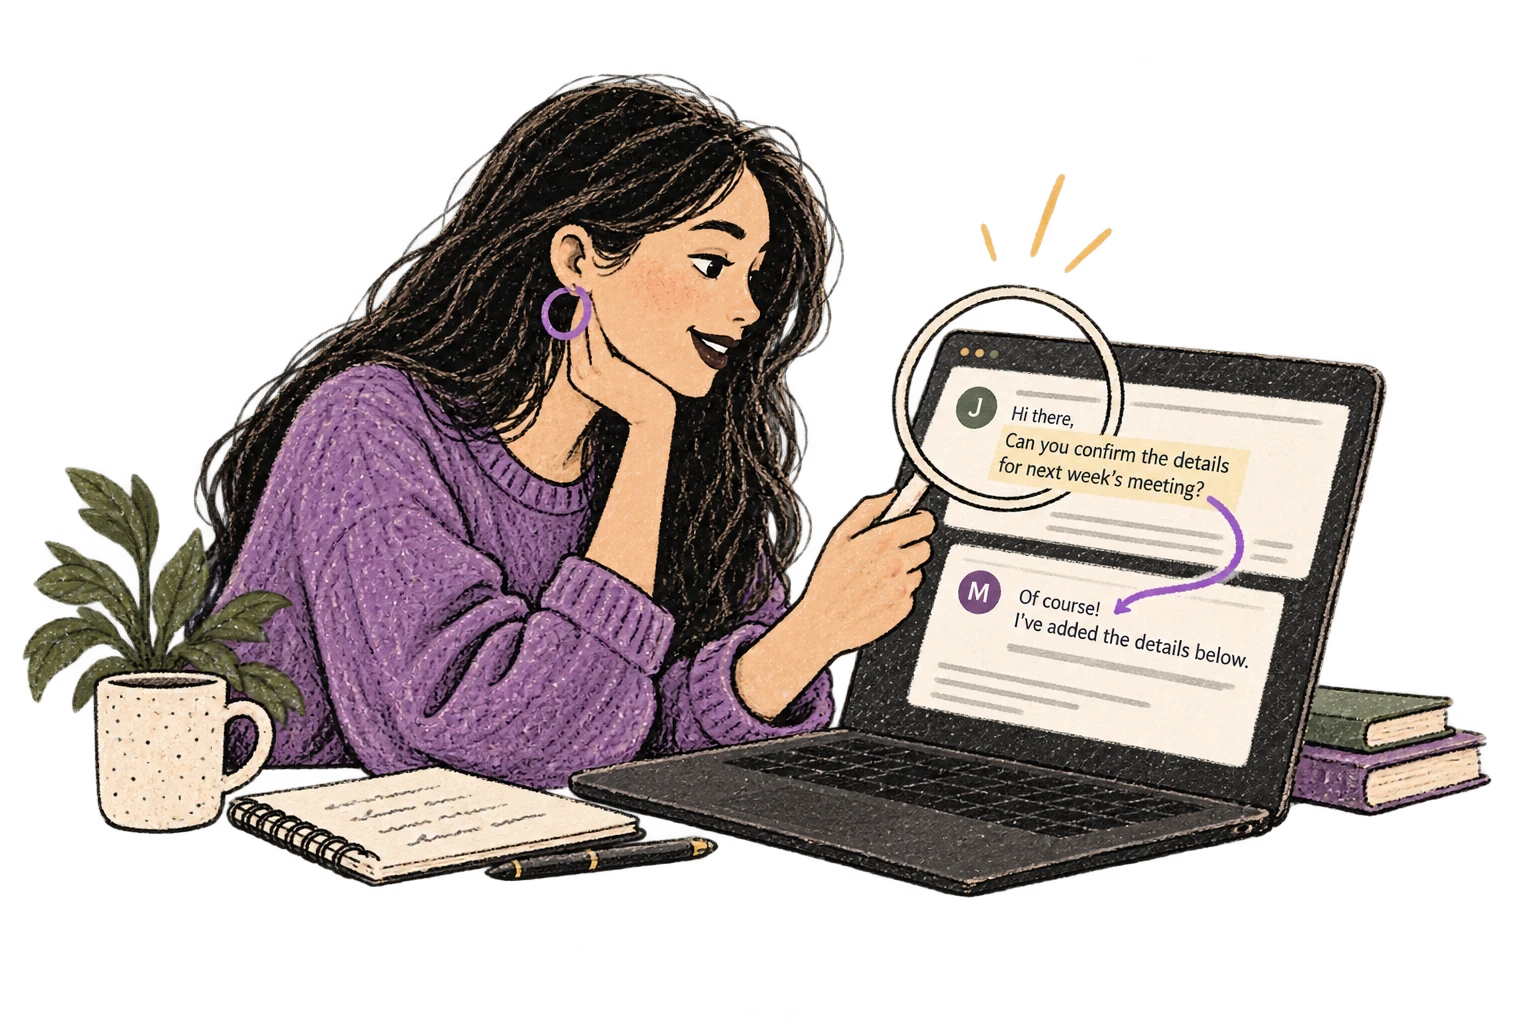
Optionally let AI see your screen for smarter responses. Reply to emails with full context, answer messages knowing the conversation history.
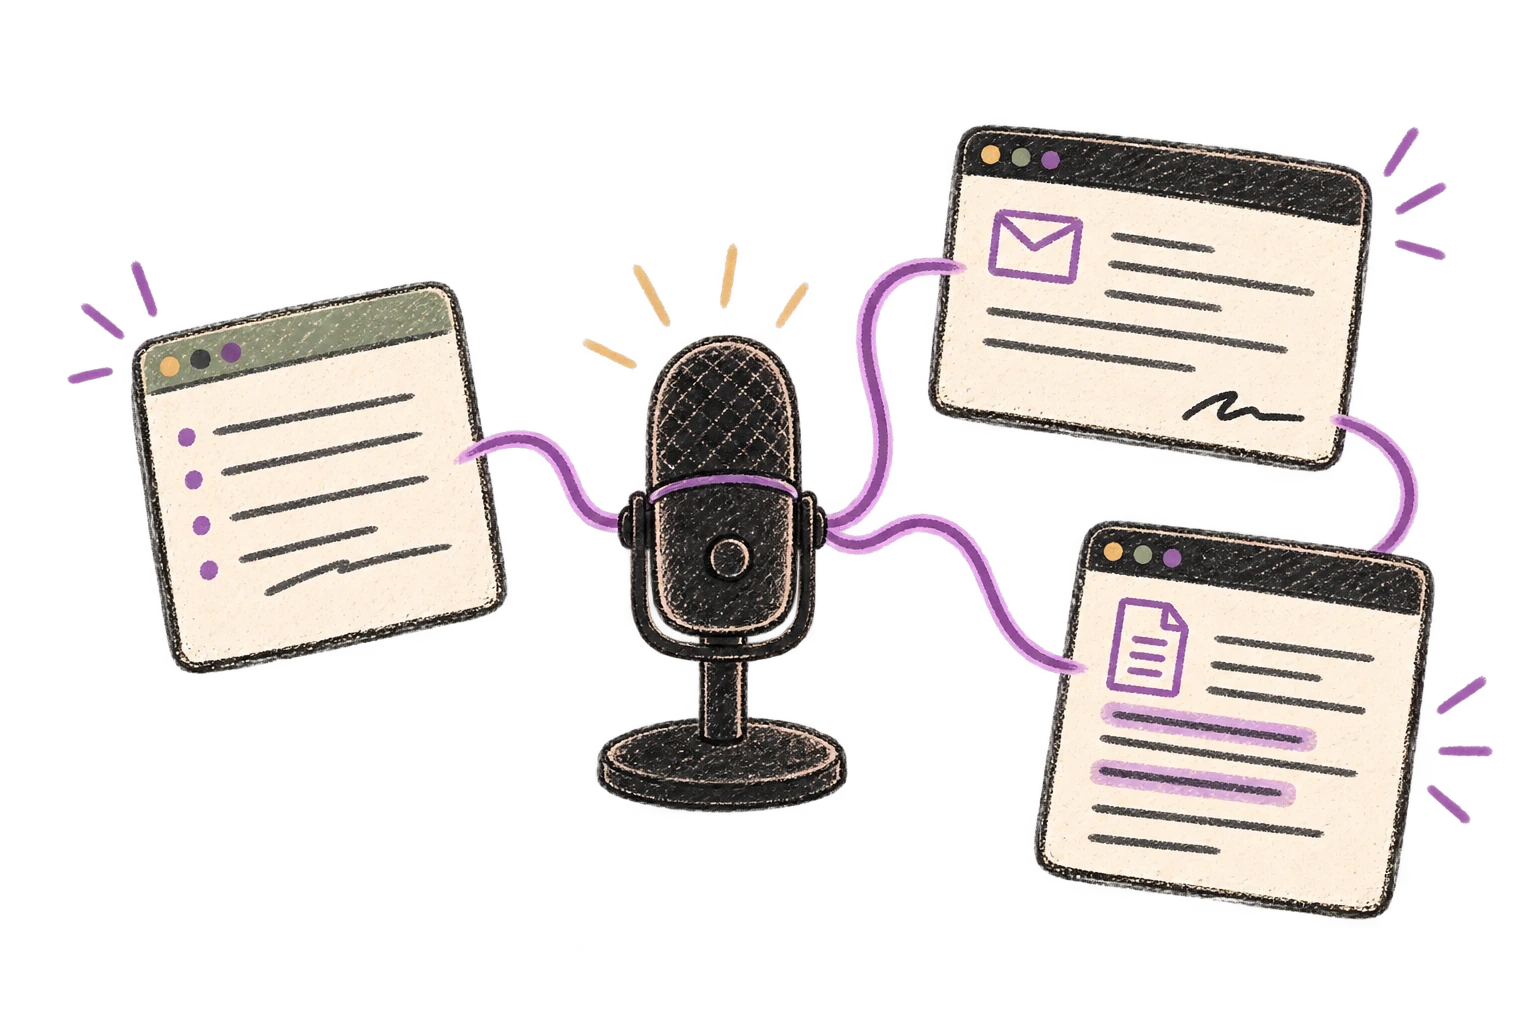
Define custom text replacements and shortcuts. Say 'work signature' to expand your full email signature, or 'my address' for your contact info.
Dictate technical documentation, READMEs, or API docs. Speaking lets you explain context, edge cases, and examples naturally—better docs with less effort.
Works with
Read this example aloud, or say something of your own.
Dictate prompts to ChatGPT, Claude, Perplexity, or any AI chatbot. Speaking naturally lets you give more context—better context means better results.
Read this example aloud, or say something of your own.
Dictate Jira tickets, Linear issues, or Asana tasks. Speak the context, acceptance criteria, and details—then move on.
Read this example aloud, or say something of your own.
Speak ideas the moment they hit you. Use Ottex anywhere to capture thoughts, then refine them later.
Works with
Read this example aloud, or say something of your own.
Reply to Slack messages 3x faster. Dictate casual updates, detailed explanations, or quick acknowledgments without switching context.
Read this example aloud, or say something of your own.
Dictate email responses with the right tone. Use context awareness to see the full thread, then speak your reply naturally.
Read this example aloud, or say something of your own.
Dictate meeting notes in real-time or right after. Capture action items, decisions, and key points while they're fresh in your mind.
Works with
Read this example aloud, or say something of your own.
Dictate standup updates, weekly reports, or project status. Speak what happened and what's next—done.
Works with
Read this example aloud, or say something of your own.
Reply to YouTube comments, Twitter threads, or social media mentions by voice. Stay engaged with your audience without the typing fatigue.
Works with
Read this example aloud, or say something of your own.
Yes. Cloud models like Gemini 3 Flash are trained on technical documentation. They handle 'Airflow DAG,' 'dbt model,' 'Spark DataFrame,' 'Kafka topic,' 'data lineage,' and thousands of other data engineering terms accurately. For project-specific terms (internal table names, custom operators), add them to your custom dictionary.
Yes. Ottex works anywhere you can type on macOS. Document issues in real-time while watching Airflow logs, write troubleshooting notes in Notion while debugging, or dictate Slack updates about pipeline status without switching context.
When you're debugging a data quality issue or pipeline failure, ChatGPT and Claude can help—but they need context. Typing a detailed explanation of your data model, the failing transformation, and what you've tried takes forever. Speaking it takes 45 seconds. More context = better debugging advice.
No. Ottex uses less than 2% CPU because it's native Swift, not Electron. Cloud transcription happens via API. When you're running dbt models or Spark jobs locally, Ottex won't compete for resources.
Yes. Work modes let you configure different formatting per app. Technical runbooks in Notion can be structured with code blocks, while Slack updates to stakeholders can be clear and jargon-free. Same voice, different output based on context.
Free forever with local models (Whisper runs on your Mac). Or bring your own API key for cloud models—most data engineers spend ~$1-3/mo. If you want zero setup, the $9/mo premium tier includes Gemini 3 Flash with 99.1% accuracy.
Download free. Use local models immediately, or add your API key for cloud quality. Start dictating pipeline docs in minutes.
Try for freeNo credit card required.