3x Faster Than Typing
Speak 150+ words per minute vs 40 wpm typing. Finish tasks in a third of the time.
Document incidents in real-time. Write runbooks faster. Debug with AI.
Read this example aloud, or say something of your own.
Your voice. Right where you work.
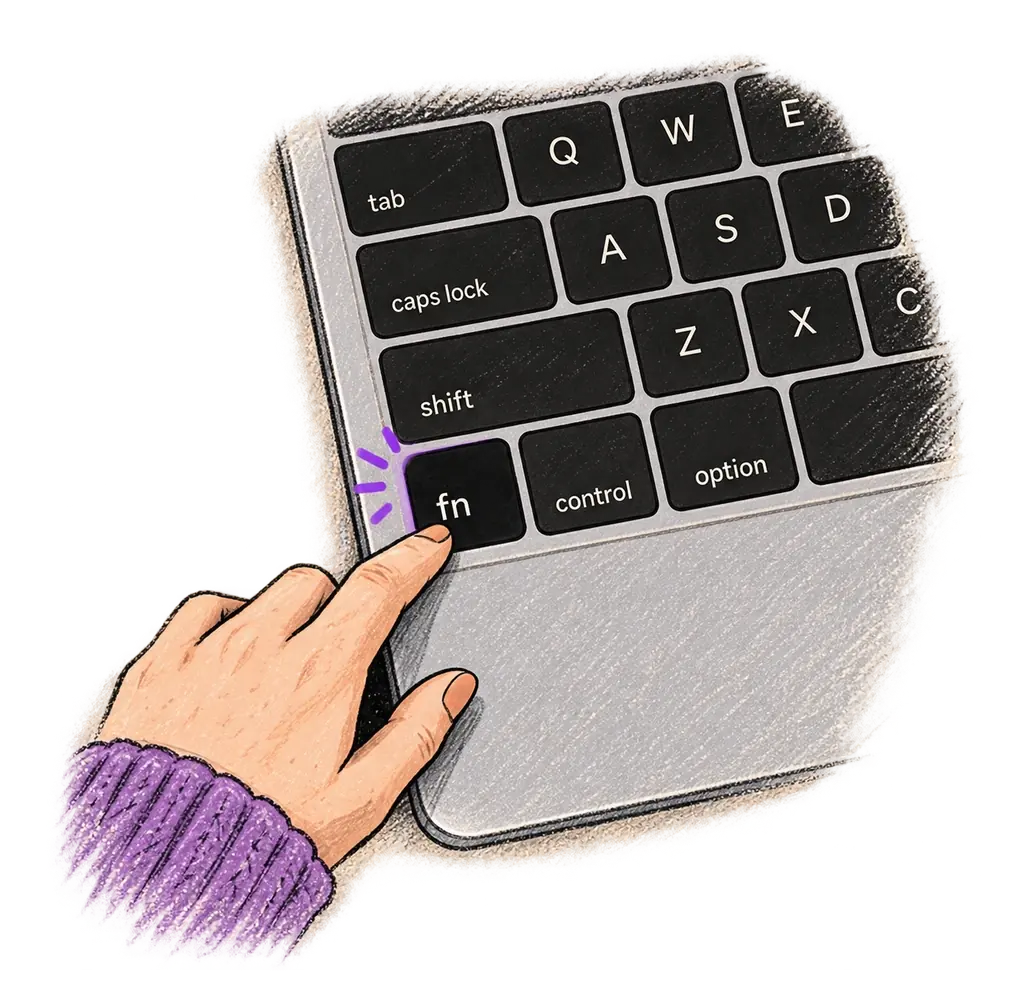
Place your cursor in any app, then hold the Fn key.
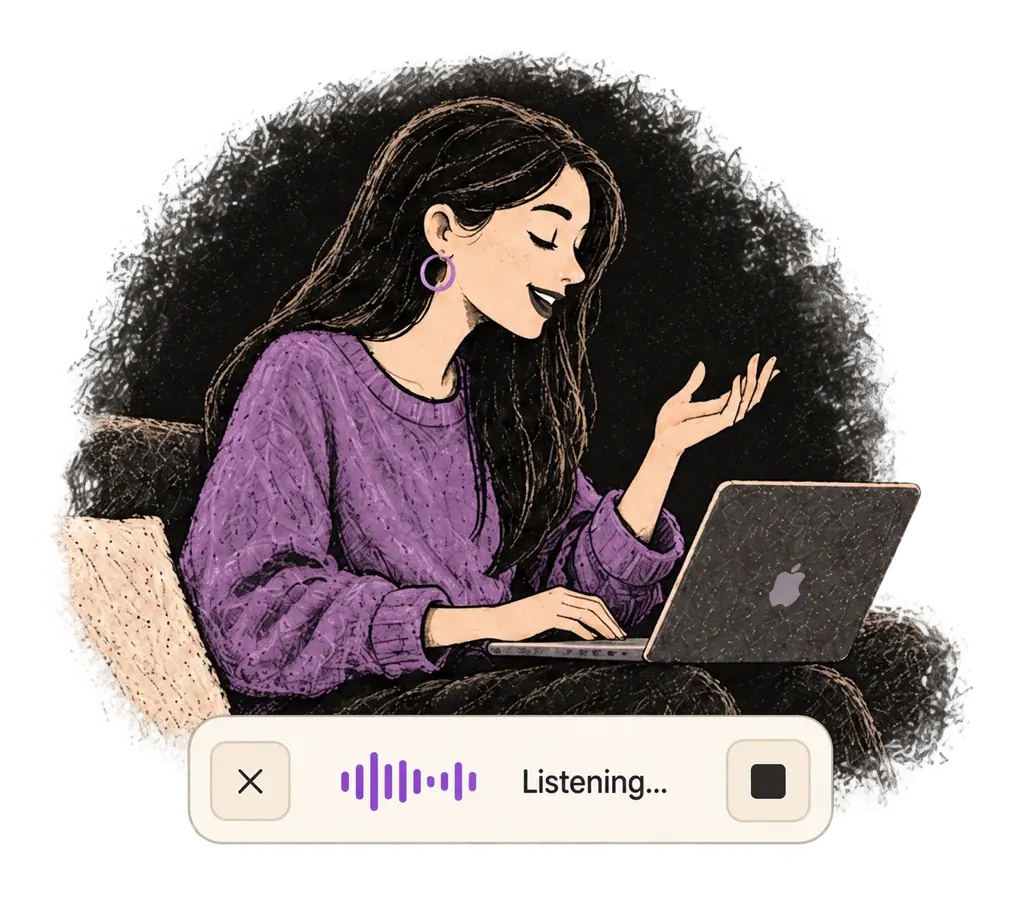
Say what you want to write. Ottex follows your saved writing rules.
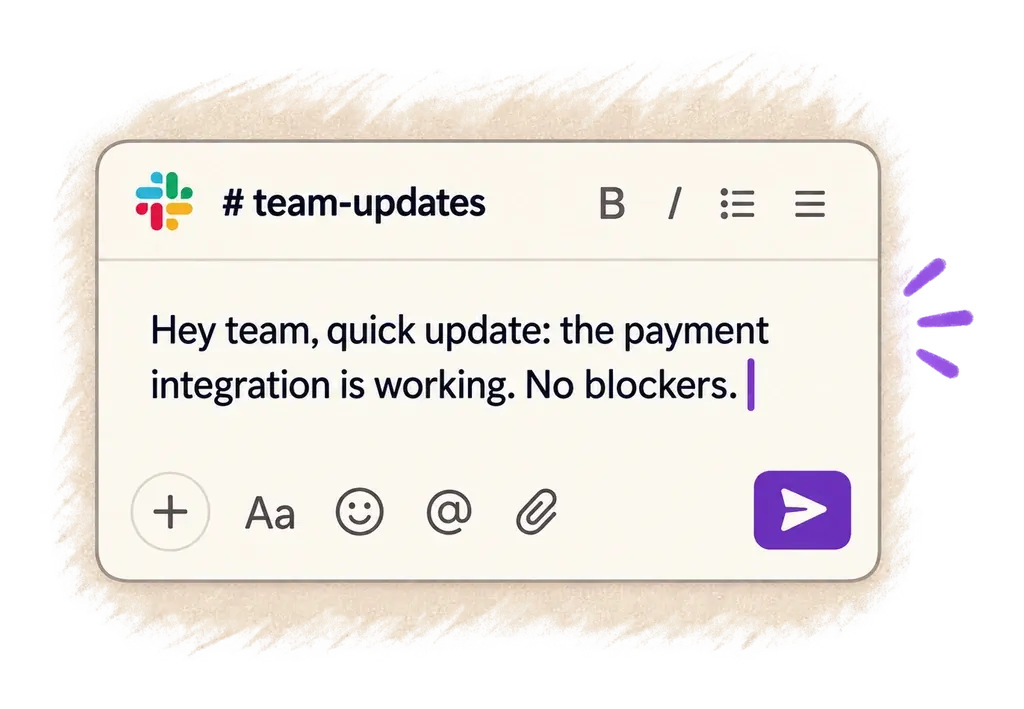
Your text appears right where your cursor is.
Concrete benefits with real-world impact
Speak 150+ words per minute vs 40 wpm typing. Finish tasks in a third of the time.
Speaking naturally gives AI agents more context than typing. Describe your intent, explain edge cases, mention file names—your voice carries nuance that typing shortcuts.
Cloud AI models excel at technical jargon, code terminology, and specialized vocabulary.
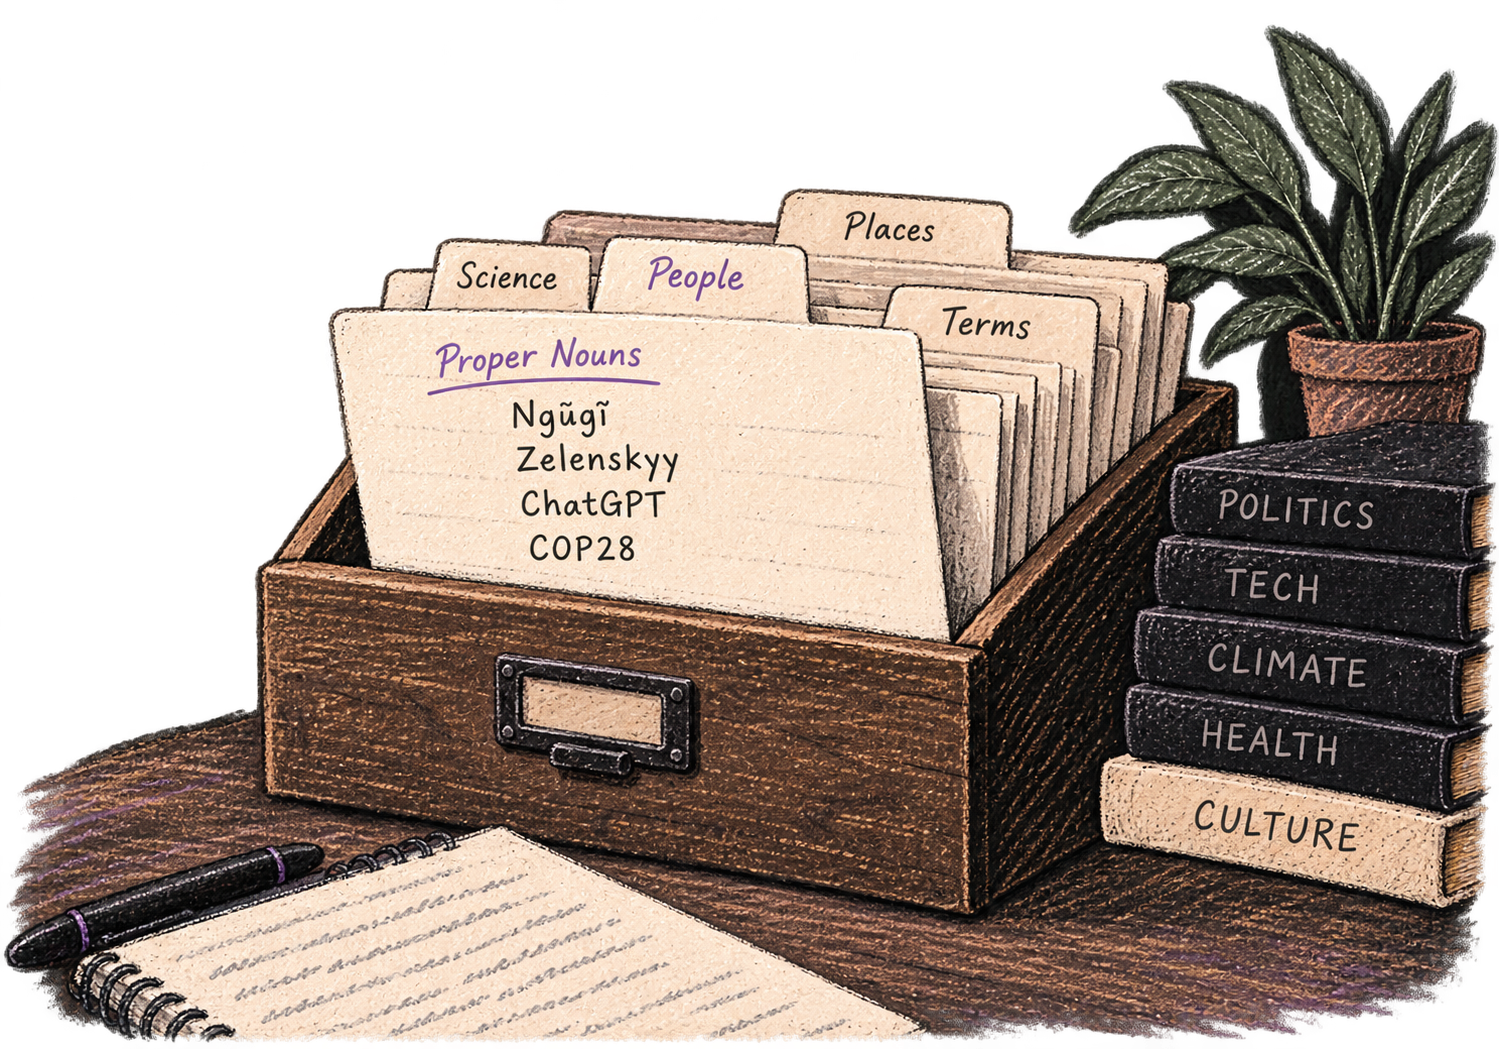
Add names, technical terms, and jargon. Ottex transcribes them accurately every time.
Transform text as you speak: 'Ottex start fix grammar Ottex end'. Edit, improve, translate—all by voice.
Say 'new paragraph', 'open quote', 'em dash', 'ellipsis'. Full formatting control by voice.
Say 'scratch that' to delete mistakes, 'actually' to rephrase. Fix errors without stopping your flow or touching the keyboard.
Dictate prompts to ChatGPT, Claude, Perplexity—anywhere you type. Better prompts, better answers.
Ottex detects which app you're in and adapts. Coding mode in Cursor, casual tone in Slack, professional in Gmail—automatic context switching.
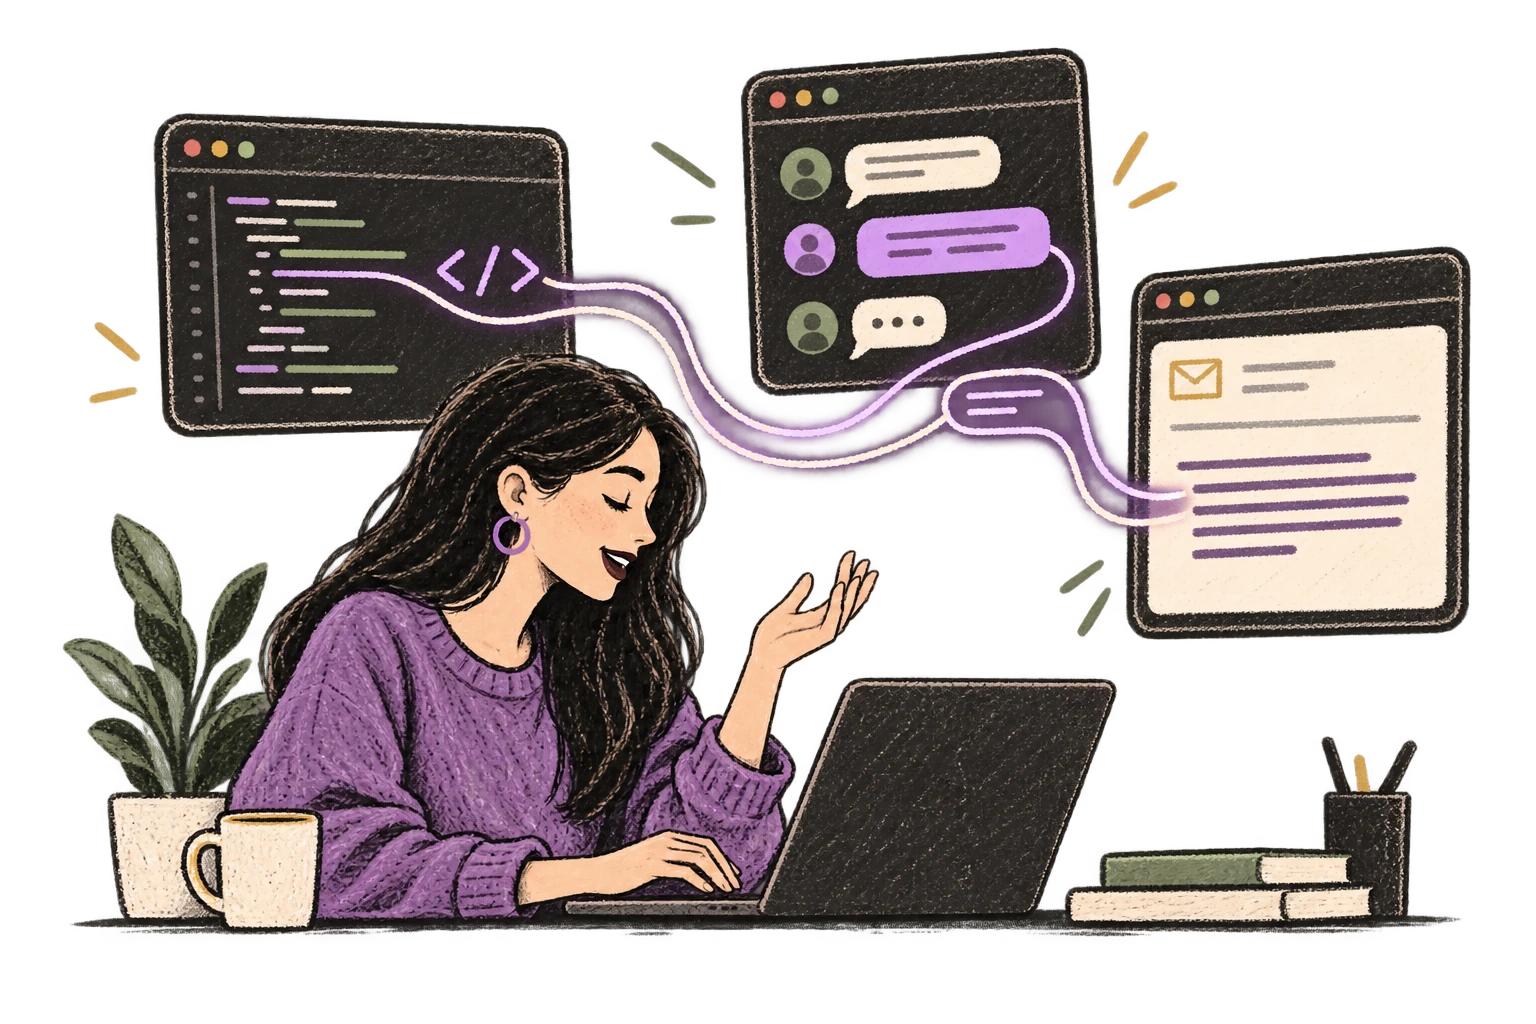
Optionally let AI see your screen for smarter responses. Reply to emails with full context, answer messages knowing the conversation history.
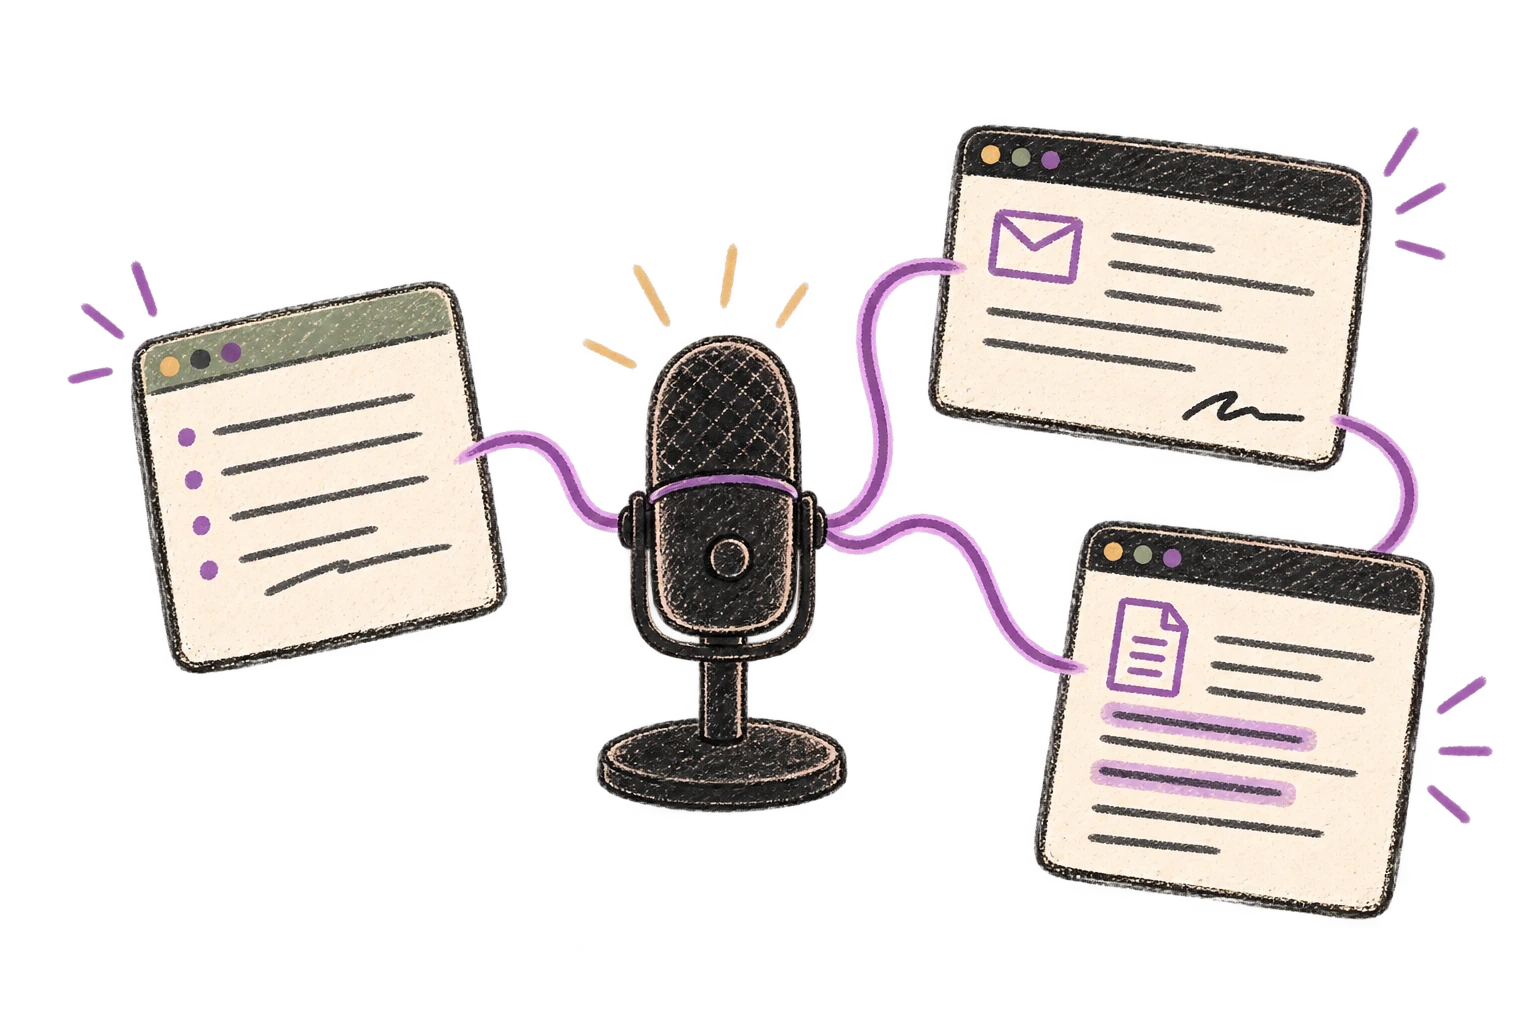
Define custom text replacements and shortcuts. Say 'work signature' to expand your full email signature, or 'my address' for your contact info.
Start recording with Option+D, use Push-to-Talk, or cancel with Esc. All shortcuts are fully configurable.
System-wide on macOS—Ottex works wherever you can type. No app-specific integrations needed.
Automatically removes filler words like 'um', 'uh', 'like', 'so' from your transcription. Get clean, professional text without verbal hesitations.
Works in VS Code, Cursor, JetBrains, Xcode—any editor. Dictate prompts to AI coding assistants.
Dictate technical documentation, READMEs, or API docs. Speaking lets you explain context, edge cases, and examples naturally—better docs with less effort.
Works with
Read this example aloud, or say something of your own.
Dictate Jira tickets, Linear issues, or Asana tasks. Speak the context, acceptance criteria, and details—then move on.
Read this example aloud, or say something of your own.
Dictate prompts to ChatGPT, Claude, Perplexity, or any AI chatbot. Speaking naturally lets you give more context—better context means better results.
Read this example aloud, or say something of your own.
Reply to Slack messages 3x faster. Dictate casual updates, detailed explanations, or quick acknowledgments without switching context.
Read this example aloud, or say something of your own.
Dictate meeting notes in real-time or right after. Capture action items, decisions, and key points while they're fresh in your mind.
Works with
Read this example aloud, or say something of your own.
Speak ideas the moment they hit you. Use Ottex anywhere to capture thoughts, then refine them later.
Works with
Read this example aloud, or say something of your own.
Dictate standup updates, weekly reports, or project status. Speak what happened and what's next—done.
Works with
Read this example aloud, or say something of your own.
Dictate detailed prompts to AI coding assistants in Cursor, Copilot, or Claude Code. Explain what you need naturally without losing your train of thought.
Read this example aloud, or say something of your own.
Yes. Cloud models like Gemini 3 Flash are trained on technical documentation and handle infrastructure terms well—Kubernetes, Terraform, Prometheus, kubectl commands, AWS service names. For your specific service names and internal tools, add them to the custom dictionary once.
Yes. Push-to-Talk mode lets you dictate in bursts—tap hotkey, speak an update, release. Your hands stay on the keyboard for kubectl commands and log analysis. Voice handles documentation while you focus on resolution.
Yes. Use local Whisper models for 100% offline transcription—nothing leaves your Mac. For cloud transcription, BYOK means audio goes directly to your API provider using your key, not through Ottex servers. You control the privacy level for sensitive documentation.
Yes, Ottex works system-wide on macOS—anywhere you can type. Terminal, VS Code, JetBrains IDEs, Slack, Notion, Confluence, GitHub, Jira. One tool for your entire DevOps workflow.
Speaking removes the friction of explaining complex system state. Instead of typing a summary, you speak the full context: recent deployments, error patterns, system metrics, what you've tried. ChatGPT and Claude give better suggestions when they have complete information. You've explained the problem in 30 seconds instead of 3 minutes of typing.
Yes. Ottex detects your active app and adjusts formatting and tone accordingly. Slack incident updates stay short and actionable. Confluence runbooks get structured formatting. Post-mortem docs get professional tone. You control the style per app.
No. Ottex uses less than 2% CPU because it's native Swift, not Electron. Cloud processing happens via API. Local models run efficiently on Apple Silicon. Your Docker containers, k9s, monitoring dashboards, and terminal sessions stay responsive.
Free with local models (Whisper runs on your Mac). With BYOK, most DevOps engineers spend $2-4/month using Gemini 3 Flash or Groq. Heavy incident months with lots of documentation might hit $5-6. Compare that to enterprise tools with per-seat pricing.
Download free. Use local models for private infrastructure docs, or add your API key for cloud transcription.
Try for freeNo credit card required.